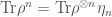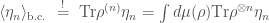
Tag Archives: free probability

The Story of the Determinant: Why the Determinant Formula is True

post by Vladislav Kargin

In his post Roland asked whether the Mai–Speicher formula for the Fuglede–Kadison determinant of a matrix semicircle survives when a constant matrix is added. With Sa=a⊗1+∑jAj⊗sjS_a=a\otimes1+\sum_jA_j\otimes s_j and η(X)=∑jAjXAj\eta(X)=\sum_jA_jXA_j, the proposed formula is

log⁡Δ(Sa−z)=−12+infb⁡{trm⁡log⁡b+12⟨a−z,(𝒞b+η)−1(a−z)⟩},𝒞b(X)=bXb,\log\Delta(S_a-z)=-\frac12+\inf_{b}\Bigl\{\operatorname{tr}_m\log b +\frac12\langle a-z,(\mathcal C_b+\eta)^{-1}(a-z)\rangle \Bigr\}, \qquad \mathcal C_b(X)=bXb,

where the infimum is over positive matrices bb with 𝒞b−η⪰0\mathcal C_b-\eta\succeq0. It is true, for every real zz. The proof is in the manuscript. Here I only want to say how I think about it, because the formula looked strange to me at first and now it looks a bit less strange.

There had to be some formula

The logarithmic potential is an integral of the Stieltjes transform. The Stieltjes transform comes from the Dyson equation G−1+η(G)=z−aG^{-1}+\eta(G)=z-a. And the Dyson equation is the Euler–Lagrange equation of a functional, the Dyson action

𝒜z(M)=−trm⁡log⁡M−12trm⁡(Mη(M))+trm⁡((z−a)M)−1.\mathcal A_z(M)=-\operatorname{tr}_m\log M-\frac12\operatorname{tr}_m\bigl(M\eta(M)\bigr) +\operatorname{tr}_m\bigl((z-a)M\bigr)-1 .

If you differentiate the action at its critical point with respect to zz, only the explicit zz contributes, and you get trm⁡G\operatorname{tr}_mG. So the action at the Dyson solution is also an integral of the Stieltjes transform, and it is not a surprise that log⁡Δ(Sa−z)=Re⁡𝒜z(G(z))\log\Delta(S_a-z)=\operatorname{Re}\mathcal A_z(G(z)). The shift aa plays no role here. It rides along with zz.

So the determinant is a critical value. The trouble is that it is the wrong kind of critical value. The action is holomorphic in MM, so the Dyson solution is a saddle of its real part, with as many directions going down as going up. A formula with an “inf⁡\inf” in it cannot come from the action directly.

The idea: free the scale

In the centered case the answer is det⁡b\det b for the matrix bb that scales η\eta to a doubly stochastic map. This suggested that GG should come with a positive “scale” also in general. It does: there is a unique b≻0b\succ0 with

G=b−1/2Ub−1/2,U unitary.G=b^{-1/2}\,U\,b^{-1/2},\qquad U\ \text{unitary}.

For scalars this is just b=1/|G|b=1/|G| and UU is the phase.

The step that was unexpected for me is to forget that bb is determined by GG and treat it as a new independent variable. Write G=−u−iγG=-u-i\gamma and consider

𝒦(b,u,γ)=trm⁡log⁡b+⟨a−z,u⟩−12⟨u,(𝒞b+η)u⟩−12⟨γ,(𝒞b−η)γ⟩.\mathcal K(b,u,\gamma)=\operatorname{tr}_m\log b+\langle a-z,u\rangle -\frac12\langle u,(\mathcal C_b+\eta)u\rangle -\frac12\langle \gamma,(\mathcal C_b-\eta)\gamma\rangle .

When bb is the true scale of −u−iγ-u-i\gamma this is the real part of the Dyson action (plus 12\frac12), by a direct computation. And the Dyson solution, together with its scale, is still a critical point of 𝒦\mathcal K in the three variables. So nothing is lost. What is gained is that the saddle has been taken apart: 𝒦\mathcal K is concave in uu and in γ\gamma, so all the descending directions sit in these two variables, and one can remove them by maximizing.

Two things that come for free

The first is the constraint. I had thought of 𝒞b−η⪰0\mathcal C_b-\eta\succeq0 as a condition somebody cleverly imposed. But look at the last term of 𝒦\mathcal K. Its supremum over γ⪰0\gamma\succeq0 is 00 if 𝒞b−η⪰0\mathcal C_b-\eta\succeq0 and +∞+\infty otherwise. The feasible set is simply the set of bb for which the problem makes sense. It is the trace that the imaginary part of GG leaves behind.

Maximizing over uu then gives exactly the function in Roland’s formula.

The second is convexity, and this is the heart of the matter. The function of bb that remains is not convex in the usual sense. It is convex along the geodesics b1/2etXb1/2b^{1/2}e^{tX}b^{1/2} of the positive cone, and it is so precisely on the feasible set. The scalar semicircle shows what this means. There the function is

Fx(b)=log⁡b+x22(b2+1),b≥1.F_x(b)=\log b+\frac{x^2}{2(b^2+1)},\qquad b\ge1 .

For positive numbers the geodesics are simply t↦bett\mapsto be^{t}, so geodesic convexity is ordinary convexity in the variable s=log⁡bs=\log b. In this variable

Fx=s+x24(1−tanh⁡s).F_x=s+\frac{x^2}{4}\,\bigl(1-\tanh s\bigr).

The first term is linear. The second is a reflected tanh⁡\tanh: it is convex for s>0s>0 and concave for s<0s<0, and its inflection point is at s=0s=0, that is, at b=1b=1, exactly the boundary of the feasible set. So the constraint that came out of the imaginary part is the same as the condition that makes the problem convex. I do not think this is an accident, but I cannot say in one sentence why it must be so.

Once we have convexity, a critical point is a global minimum, and the critical point is the scale of the Dyson solution. This is the whole proof in the upper half-plane. To get to the real axis one adds εtrm⁡γ\varepsilon\operatorname{tr}_m\gamma to 𝒦\mathcal K, which adds a positive term of order ε2\varepsilon^2 to the function of bb, and lets ε→0\varepsilon\to0. Everything is monotone, and one never needs to know what the minimizers do.

What the picture looks like

In the scalar example the equation Fx′(b)=0F_x'(b)=0 is b+1/b=|x|b+1/b=|x|, which is the Dyson equation for b=1/|G|b=1/|G|. For |x|>2|x|>2 it has a solution with b>1b>1. For |x|<2|x|<2 it has none, the minimum sits at the wall b=1b=1, and its value is x2/4x^2/4, as it should be.

The same holds for matrices, at least at points where the density is nondegenerate. Outside the spectrum the minimizer is in the interior of the feasible set. Inside the spectrum it is on the boundary, and the kernel of 𝒞b−η\mathcal C_b-\eta at the minimizer contains γ=−Im⁡G\gamma=-\operatorname{Im}G. In other words, the spectrum is where the constraint is active, and the density of states is its Lagrange multiplier. This is the form in which I remember the result.

What I do not understand

Is the infimum attained at spectral edges, and at points where the matrix density is nonzero but singular? I do not know. The scales bεb_\varepsilon might run away, and at points where the density blows up they do. It would be nice to read the type of the singularity from how fast they run.

The question I find most interesting is about the Brown measure. By hermitization the formula applies to any S=a0⊗1+∑ai⊗siS=a_0\otimes1+\sum a_i\otimes s_i with arbitrary matrices aia_i and any complex zz. For each fixed bb the function under the infimum is a quadratic polynomial in Re⁡z\operatorname{Re} z and Im⁡z\operatorname{Im}z. So the logarithmic potential of the Brown measure is an infimum of quadratic polynomials over a fixed convex set.

Now we can ask whether the minimizer bzb_z sits in the interior or on the boundary of the feasible set. By the picture above this should detect the spectrum of SS: if S−zS-z is invertible, the minimizer is in the interior. Is this enough to detect the support of the Brown measure? That is, is the Brown measure of SS supported exactly where the constraint is active? For general operators the spectrum can be strictly larger than the support of the Brown measure. Haagerup and Larsen found this for RR-diagonal elements, where it happens when the element has an inverse which is in L2L^2 but is not bounded. Miyagawa has recently shown that a rational function in free semicirculars which is in L2L^2 is bounded, so this mechanism is not available here, and he asks whether there is any gap at all in that setting. Hall and Ho proved that there is none for a self-adjoint element plus a free elliptic one. For matrix semicirculars I do not know the answer. If there is no gap, the variational problem should show it: one would have to prove that the potential cannot be harmonic at a point where the constraint binds.

While this post was waiting to appear, Sheng Yin sent me a different formula for the same determinant, also found with the help of AI. In his formula the infimum is over all positive matrices, with no constraint, and it is attained exactly when the operator is invertible; in Roland’s formula the minimizer sits on the wall inside the spectrum. For self-adjoint coefficients the two are related by an explicit change of variables, which turns the free variable of one into the constrained variable of the other. His manuscript is on Hexagon (hexagon:2610.00180). How the two pictures fit together in general is something we would like to understand.

I should add that I worked on this in long conversations with language models. It felt like working with a co-author, and I cannot separate who contributed what. The responsibility for the correctness is mine.
A Story of the Determinant of Operator-Valued Semicircular Elements

Operator-valued semicircular elements are the powerhouse of free probability and random matrix theory. In particular, the intrinsic freeness principle typically replaces random matrices by operator-valued semicircular elements and shows that, in many respects, the former are close to the latter. Thus it is important to understand as much as possible about operator-valued semicirculars.

An operator-valued semicircular element – say over B=Mm(ℂ)B=M_m(\mathbb C) – is of the form

S=a⊗1+∑i=1nai⊗siwitha,a1,…,an∈Mmsa(𝐂),S=a\otimes 1+\sum_{i=1}^n a_i\otimes s_i\qquad\text{with} \qquad a,a_1,\dots,a_n\in M_m^{sa}(\mathbf C),

where s1,…,sn s_1,\dots,s_n are free semicirculars. We denote by trm{\rm tr}_m the normalized matrix trace on BB, and by τ\tau the trace on the algebra, where the sis_i live. All information about such an element SS is contained in its mean

(id⊗τ)[S]=a ({\rm id} \otimes \tau)[S]=a

and its covariance

η(b)=:(id⊗τ)[(S−a)b(S−a)]=∑i=1naibai.\eta(b)=:({\rm id}\otimes \tau)[(S-a)b(S-a)]=\sum_{i=1}^n a_i b a_i.

The covariance η\eta is a completely positive map from BB to BB.

We also know how, in principle, to calculate the distribution μS\mu_S of SS. Its scalar-valued Cauchy transform is

gS(z)=(tr⁡m⊗τ)[(z1−S)−1].g_S(z)=(\tr_m\otimes \tau)[(z1-S)^{-1}].

This can be extracted from the operator-valued Cauchy transform

GS(b)=(id⊗τ)[(b−S)−1]G_S(b)=({\rm id}\otimes\tau)[(b-S)^{-1}]

simply by

gS(z)=tr⁡m[GS(z1)].g_S(z)=\tr_m[G_S(z1)].

And GSG_S is determined by the nice quadratic matrix-valued equation, usually called the Dyson equation,

(b−a)⋅GS(b)=1+η(GS(b))⋅GS(b). (b-a)\cdot G_S(b)=1+\eta(G_S(b))\cdot G_S(b).

So everything is determined by mean and covariance. Of course, some quantities are easier, others harder to extract in a meaningful way. For moments of SS, for example, one has the operator-valued free version of the Wick/Isserlis formula. The operator norm of SS, on the other hand, is not so easily accessible. In principle, this is given by the asymptotics of high moments, but that is not very concrete. So the following celebrated formula of Franz Lehner

λmax⁡(a⊗1+∑i=1nai⊗si)=infb∈B,b>0⁡λmax⁡(b+a+η(b−1))\lambda_{\max} \left(a\otimes 1+\sum_{i=1}^n a_i\otimes s_i\right) = \inf_{b\in B, b \gt 0}\lambda_{\max} \left(b+a+\eta(b^{-1})\right)

comes as a nice surprise, as it reduces the upper spectral edge of the infinite-dimensional SS to a variational problem for the same quantity on the finite-dimensional matrix algebra BB. Here λmax⁡\lambda_{\max} denotes the upper edge of the spectrum; for positive aa, Lehner’s original formulation gives the corresponding operator norm.

A few years ago together with Tobias Mai I was trying to understand the determinant (more precisely, the Fuglede–Kadison determinant) of an operator-valued semicircular element, in order to get some info about the accumulation of mass of the distribution of such a semicircular element close to zero. And we succeeded in finding a nice formula in terms of the covariance; more precisely the determinant was essentially given by the capacity of the covariance map. Capacity here is the quantity introduced by Gurvits in connection with operator scaling; it should not be confused with the various notions of channel capacity in quantum information. Unwinding this notion of capacity one can write our result concretely as

Δ(∑i=1nai⊗si)=e−1/2⋅infb∈B,b>0⁡Δ(b⋅η(b−1))1/2.\Delta(\sum_{i=1}^n a_i\otimes s_i) = e^{-1/2}\cdot \inf_{b\in B, b>0} \Delta\left(b\cdot \eta(b^{-1})\right)^{1/2}.

Δ\Delta is here the Fuglede–Kadison determinant, which reduces in the finite-dimensional situation to

Δ(b)=det⁡(|b|)1/mforb∈Mm(ℂ).\Delta(b)=\det (\vert b\vert)^{1/m}\qquad\text{for}\qquad b\in M_m(\mathbb C).

As you see, our result is only for mean a=0a=0. But in this case it has a striking similarity with Lehner’s formula:

‖∑i=1nai⊗si‖=infb∈B,b>0⁡‖b+η(b−1)‖,\| \sum_{i=1}^n a_i\otimes s_i\| = \inf_{b\in B, b>0} \left\|b+\eta(b^{-1})\right\|,

And of course it raises the question: Can we extend our formula also to the case of general mean. We thought a little bit about this way back then, but did not see how to do this.

Now, in the times of AI hype, it is tempting to come back to this question and ask ChatGPT what it has to say on this. And actually, it has something to say. It proposes the following generalization

Δ(a⊗1+∑i=1nai⊗si)=e−1/2infb>0, 𝒞b−η⪰0⁡Δ(b)exp⁡{12⟨a,(𝒞b+η)−1(a)⟩2},\Delta\left(a\otimes 1+\sum_{i=1}^n a_i\otimes s_i\right) = e^{-1/2} \inf_{b \gt 0,\ \mathcal C_b-\eta\succeq 0} \Delta(b)\, \exp\left\{ \frac12 \left\langle a, (\mathcal C_b+\eta)^{-1}(a) \right\rangle_2 \right\},

where

𝒞b(x)=bxb,and⟨x,y⟩2=trm⁡(x∗y)forx,y∈Mm(ℂ)\mathcal C_b(x)=bxb,\qquad\text{and}\qquad\langle x,y\rangle_2 = \operatorname{tr}_m(x^*y)\qquad \text{for} \qquad x,y\in M_m(\mathbb C)

is the Hilbert-Schmidt inner product.

The condition 𝒞b−η⪰0\mathcal C_b-\eta\succeq 0 means positivity as an operator on the Hilbert–Schmidt space Mm(ℂ)M_m(\mathbb C), i.e.

⟨x,𝒞b(x)⟩2≥⟨x,η(x)⟩2,or equivalentlytrm⁡(x∗bxb)≥trm⁡(x∗η(x)),for all x∈Mm(ℂ).\left\langle x,\mathcal C_b(x)\right\rangle_2 \geq \left\langle x,\eta(x)\right\rangle_2,\qquad\text{or equivalently}\qquad \operatorname{tr}_m(x^*bxb) \geq \operatorname{tr}_m\left(x^*\eta(x)\right), \qquad\text{for all }x\in M_m(\mathbb C).

ChatGPT also produces what it claims is a proof of all this — note that even the reduction of this to my formula with Tobias in the case of a=0a=0 is non-trivial — and makes some remarks on the relevance for the Brown measure of an operator-valued circular element. Recall that the Brown measure of an operator TT is encoded by the logarithmic potential

z↦log⁡Δ(T−z1).z\mapsto \log \Delta (T-z1).

So understanding determinants of shifted operators is exactly what one needs here.

All this looks somehow reasonable, but not very enlightening; and even if I had a Lean certificate for all this (which I don’t), I would still not be too satisfied.

So let’s talk about all this and hope that, together, we can get a better understanding of what is really going on.

Doing Mathematics with AI — but How?

AI is revolutionizing mathematics, and it will not go away. So somehow we have to arrange ourselves with it and find our way of doing mathematics under these changed conditions.

I am of course also fascinated by asking AI (ChatGPT in my case) to solve all my problems. And sometimes there are indeed answers which seem to be okay and which promise some real progress. But those answers are usually complicated and quite technical, and I don’t really feel like becoming a little helper and argument checker for AI.

I agree with many voices saying that asking the meaningful questions, and understanding and presenting the answers, will remain some of the main tasks for us. But this should happen in a way that we still feel good about going along with it. For me this means that I would like to take from AI mainly some ideas, but then think myself about whether they could be true, what they actually mean, how one could prove them, and what is the best way to present them and convince others.

Of course, like everybody else, I don’t have a final answer to how this should work in practice, or whether this is a route which will help mathematics to survive in anything resembling its present form.

Anyhow, I suppose we just have to try different routes. Here is one experiment I would like to make.

At the moment I am thinking about determinants of operator-valued semicircular elements. Together with Tobias Mai, we derived a few years ago a formula for the determinant of such an element S in terms of its covariance map. This was, however, for the case of vanishing mean of S, and I wondered whether there could be a nice and useful extension to the case of general mean.

Okay, so I asked ChatGPT. And it did what two years ago would have seemed totally out of range, but has now become almost ordinary: it gave me an answer, proved it, and also made some comments on possible implications for questions about the Brown measure of operator-valued circular elements.

It even wrote a manuscript about all this.

I could now just put my name on it, say that the ideas were developed in conversations with AI, and declare that I take full responsibility for the results. But this does not feel right to me. And, more importantly, it does not feel very satisfying.

So here is what I would rather like to do.

I will give some background, explain what ChatGPT proposes as the answer, and then open the problem for public discussion: Is the statement correct? Is it perhaps obvious? How is it related to things that somebody already knows? What is the right proof? And what other interesting questions or conjectures might come out of it?

My dream would be that the answers — and also the questions — are actually self-thought, and not just copies of something another AI conversation produced. Of course everybody could now ask AI about the problem and perhaps produce a paper on it. But this should not be about publishing or priority. It should be about understanding.

Maybe one could think of it as telling a mathematical story together, in a somewhat grassroots way: somebody starts with a question, somebody else recognizes a connection, another person finds an argument, somebody points out that the whole thing is wrong, or suggests the right formulation, and gradually we understand what is really going on. Of course, we can use AI in the background for information, references, or inspiration. But AI should not tell the story.

I have no idea whether this will work.

But let us try.

In my next post I will give the concrete mathematical problem and the beginning of the story.

The noncommutative Edmonds’ problem revised: how to calculate the inner rank of matrices in noncommuting variables

Update: The paper has now been published in Foundations of Computational Mathematics as an open access article. Here is a link.

My paper with Johannes and Tobias on the noncommutative Edmonds’ problem has got a total makeover; the new revised version appeared just on the arXiv. It relies now heavily on the recent results of Tobias and mine on the Fuglede-Kadison determinant of matrix-valued semicircular elements. But also, the organization of the paper is now much more reader-friendly – at least we hope so. Everything you need to know can be gotten from the first three sections; if you need proofs, read the rest.

Let me first recall the noncommutative Edmonds’ problem. Consider a matrix

A=a_1\otimes x_1+\ldots+a_n\otimes x_n,

where the x_i are noncommuting variables and the a_i are arbitrary matrices of the same size N; N is fixed, but arbitrary.

The noncommutative Edmonds’ problem asks whether A is invertible over the noncommutative rational functions in the x_i; this is equivalent (by deep results of Cohn) to asking whether A is full, i.e., its noncommutative rank is equal to N. The noncommutative rank is here the inner rank rank(A), i.e., the smallest integer r such that we can write A as a product of an Nxr and an rxN-matrix. This fullness of the inner rank can also be equivalently decided by a more analytic object: to the matrix A we associate a completely positive map

\eta:M_N(\mathbb{C})\to M_N(\mathbb{C}),\qquad \eta(b):=\sum_{i=1}^n a_iba_i^*.

In terms of \eta, the fullness condition for A is equivalent to the fact that \eta is rank non-decreasing (here we have of course the ordinary commutative rank on the complex NxN-matrices).

This noncommutative Edmonds’ problem has become quite prominent in recent years and there are now a couple of deterministic algorithms; see, in particular, the work of Garg, Gurvits, Oliveira and Widgerson.

Let me now recall our noncommutative probabilistic approach to the noncommutative Edmonds’ problem, by replacing the formal variables by concrete operators on infinite-dimensional Hilbert spaces. And a particular nice, and our favorite, choice for the analytic operators are freely independent semicircular variables s_1,\dots,s_n, which are the noncommutative analogues of independent Gaussian random variables. In the case where all the a_i are selfadjoint, the matrix

S=a_1\otimes s_1+\ldots+a_n\otimes s_n

is a matrix-valued semicircular element.

Since one can reduce the general case to the selfadjoint one, it suffices to consider in the following the selfadjoint situation. Then the corresponding S is also a selfadjoint operator, hence its distribution is a probability measure on the real line. By our work of the last ten years or so we know that the invertibility of the formal matrix A over the noncommutative rational functions is equivalent to the invertibility of S as an unbounded operator. But this is equivalent to the question whether S has a trivial kernel, which is equivalent to the question whether its distribution has no atom at zero.

And we know how to calculate the distribution \mu of our matrix-valued semicircular element S. Namely its Cauchy transform g(z), that is, the analytic function

g(z)=\int_{\mathbb{R}} \frac 1{z-t}d\mu(t)

on the complex upper half plane is of the form

g(z)=\frac 1N \text{Tr}(G(z))

where G(z) is given as the unique solution of the matrix-valued equation

zG(z)=1+\eta(G(z)) G(z),

in the lower half-plane of the NxN-matrices. One should note that for each z in the upper complex half plane there is (by some old results of mine with Reza Rashidi Far and Bill Helton) exactly one solution G(z) in the complex lower half-plane of the matrices. And, finally, we know that \mu can have an atom only at zero, and the inner rank of A is related to the mass of this atom; more precisely,

\text{rank}(A)=N(1-\mu(\{0\})).

So it seems, problem solved: Calculate the Cauchy transform and use the Stieltjes inversion formula to get the mass of the distribution at zero. We can even make this very concrete; what we need to consider is

\theta(y):= - y \Im g(iy))

in the limit where the positive real number y tends to zero. This limit is the mass of the atom at zero.

This is nice, but of course we cannot calculate anything analytically here, but have to rely on numerical approximations. So the question is, for which y should we calculate \theta(y) with which accuracy to be able to make a justified statement about the mass of the atom. And this is were things are getting tricky, but also nice.

Consider, for example, the matrix-valued semicircular element

\begin{pmatrix} s_1 + 2s_4& s_1 + s_3 + s_4& s_1 - s_2 + s_4& s_1\\ s_1 + s_3 + s_4& s_1 + s_3& s_1 - s_2 + s_3& s_1 + s_3 - s_4\\ s_1 - s_2 + s_4& s_1 - s_2 + s_3& s_1 - 2s_2& s_1 - s_2 - s_4\\ s_1& s_1 + s_3 - s_4& s_1 - s_2 - s_4& s_1 - 2s_4 \end{pmatrix}

If you want to know how we can get out of our machinery that the atom at zero of its distribution has mass 0.5 (that is, its noncommutative rank is 2), have a look at the revised version of our paper!

What do determinants tell us about the eigenvalues of integer-valued matrices? — And what can we say about Fuglede-Kadison determinants of operator-valued semicircular elements?

Consider a matrix with integer entries, like

B=\begin{pmatrix} 1&2&1&3\\ 2&2&1&1\\ 1&1&2&3\\ 3&1&3&1 \end{pmatrix}

How can we convince ourselves that there are no two eigenvalues close to zero; say, you should convince me that two eigenvalues both with absolute value smaller than 0.1 are not possible. Of course, we should not calculate the eigenvalues but decide on this by arguments as soft as possible.

It is easy to get upper bounds for eigenvalues by the operator norm or the normalized trace of the matrix – those are quantities which are usually easy to control.

Not so clear are lower bounds, but actually it’s the determinant which will be of good use here. Namely, since the determinant is the product of the eigenvalues, knowing a lower bound for the absolute value of the determinant, together with the above mentioned easy upper bounds, gives lower bounds for the absolute values of the non-zero eigenvalues. In this example, we can calculate the determinant as -1, estimate the norm against the Frobenius norm of \sqrt{60} and can derive from this that no two eigenvalues of absolute value smaller than 0.1 are possible, because otherwise we would have the following estimate

\vert \text{det}(B)\vert \leq 0.1\times 0.1\times \sqrt{60}\times\sqrt{60}=.6

which contradicts the fact that \vert \text{det}(B)\vert=1.

Maybe you don’t like so much the idea of having to calculate the determinant, as this does not feel so soft. Assume however that I told you, as an oracle, that the matrix is invertible, then you can forget about calculating the determinant and just argue that the determinant of a matrix with integer entries must be an integer, too, and since it cannot be zero you can conclude that it must in absolute value at least be 1; and so you can repeat the above estimate.

Those observations are of course not restricted to the above concrete example; actually, I have hopefully convinced you that no invertible matrix with integer entries can have too many eigenvalues close to zero, and the precise estimate depends on the matrix only through its operator norm.

This kind of reasoning can actually be extended to “infinite-dimensional matrices”, which means for us operators in a finite von Neumann algebra. There we are usually interested in the distribution of selfadjoint operators with respect to the trace and in recent work with Johannes Hoffmann and Tobias Mai it has become important to be able to decide that such distributions do not accumulate too much mass in a neighborhood of zero. In finite von Neumann algebras there exists also a nice version of the determinant, named after Fuglede and Kadison, and the main question is whether the above reasoning survives also in such a setting. And indeed, it does for the operators in which we are interested. But this is for reasons which are still nice, but quite a bit more tricky than for ordinary matrices.

The operators we are interested in are operator-valued semicircular elements of the form S=\sum a_i\otimes s_i, where the s_i are free semicircular elements and the a_i are ordinary mxm matrices, with the only restriction that their entries are integers. We assume that such an S is invertible (as an unbounded operator) ; one can show that then its Fuglede-Kadison determinant \Delta(S) is not equal to zero. The main question is whether we have a uniform lower estimate for \Delta(S) away from zero. As there is now no formula for the determinant in terms of the entries of the matrix S, the integer values for the entries of the a_i are of no apparent use. Still we are able to prove the astonishing fact that for all such invertible operator-valued semicircular operators their Fuglede-Kadison determinant \Delta(S) is always \geq e^{-1/2}.

For all this and much more you should have a look at my newest paper Fuglede-Kadison determinants of matrix-valued semicircular elements and capacity estimates with Tobias. If you need more of an appetizer, here is also the abstract of this paper: We calculate the Fuglede-Kadison determinant of arbitrary matrix-valued semicircular operators in terms of the capacity of the corresponding covariance mapping. We also improve a lower bound by Garg, Gurvits, Oliveira, and Widgerson on this capacity, by making it dimension-independent.

If this is still not enough to get you interested, maybe a concrete challenge will do. Here is a conjecture from our work on the limiting behavior of determinants of random matrices.

Conjecture: Let m and n be natural numbers and, for each i=1,…,n, an mxm-matrix a_i with integer entries be given. Denote by \eta the corresponding completely positive map

\eta:M_m(\mathbb{C})\to M_m(\mathbb{C}), \quad b\mapsto \eta(b):=\sum_{i=1}^n a_iba^*_i

Assume that \eta is rank non-decreasing. Then consider n independent GUE random matrices X^{(N)}_1,\dots,X^{(N)}_n and let A_N denote the Gaussian block random matrix

A_N=\sum_{i=1}^n a_i\otimes X^{(N)}_i

of size mN x mN. We claim that A_N is invertible for sufficiently large N and that

\lim_{N\to\infty}\text{det}(A_NA_N^*)^{1/N}=\text{cap}(\eta)e^{-m},

where the capacity \text{cap}(\eta) is defined as the infimum of \text{det}(\eta(b)) over all b\in M_m(\mathbb{C}) for which det(b)=1.

Free probability, between math and physics (and also machine learning) – some updates

In the recent post of a similar title I mentioned some papers which related physics problems (eigenstate thermalization hypothesis or Open Quantum SSEP) with free probability. Let me point out that the title of the preprint by Hruza and Bernard has been changed to “Coherent Fluctuations in Noisy Mesoscopic Systems, the Open Quantum SSEP and Free Probability” and that there are some new and follow up preprints in this directions, namely “Spectrum of subblocks of structured random matrices: A free probability approach“, by Bernard and Hruza, and also “Designs via free probability“, by Fava, Kurchan, Pappalardi. In all of them free cumulants and their relations to random matrices play an important role. Not too surprisingly, I find this very interesting in general, but also in particular, as during my voyage in the machine learning world I became a bit obsessed with the fact that free cumulants are given by the leading order of classical cumulants of the entries of unitarily invariant matrix ensembles (with a “cyclic” or “loop” structure of the indices). This seems to be highly relevant – though, at the moment I am not actually sure for what exactly.

Anyhow, if anybody is interested in this, in the last lecture of my machine learning course I give a very high level survey on these relations, and in the video on Gaussian equivalence principle in the same course I talk about a more concrete model of this in the random features model context.

Black hole, replica trick, de Finetti and free probability

(guest post by Jinzhao Wang)

Hawking famously showed that black holes radiate just like a blackbody. Behaving like a thermodynamic object, a black hole has an entropy worth a quarter of its area (in units of the Planck area), which is now known as the Bekenstein-Hawking (BH) entropy. Through several thought experiments, Bekenstein already reached this conclusion up to the 1/4 prefactor before Hawking’s calculation, and he also reasoned that a black hole is the most entropic object in the universe in the sense that one cannot pack entropy more efficiently in a region bounded by the same area with the same mass than a black hole does. This is known as the Bekenstein bound. As for Hawking, the BH entropy can be deduced from the gravity partition function computed using the gravitational path integral (GPI), just like how entropy is derived from the partition function in statistical physics. 

However, Hawking’s discovery led to a new problem that put the fundamental principle of physics in question, that the information carried by a closed system cannot be destroyed under evolution. This cherished principle is respected by the unitarity in quantum theory.  On the other hand, since the radiation has a relatively featureless thermal spectrum, it cannot preserve all the information a star contains before it collapses into a black hole nor the information carried by the objects that later fall into it. If the radiation is all there is after the complete evaporation, the information is apparently lost. If we are not willing to give up our well-established theories, one way out is to speculate that the black hole never really evaporates away but it somehow stops evaporating and becomes a long-living remnant when it has shrunk to the Planckian size. All the entropy production is then due to the correlation with the remaining black hole. While this could be plausible, there is already tension long before the black hole approaches its end life.  If we examine the radiation entropy after the black hole passes its half-life, the radiation entropy keeps rising according to Hawking and they have to be attributed to the correlation with the remaining black hole. This means that the mid-aged black hole has to be as entropic as the radiation but this is impossible without violating the Bekenstein bound. In fact, Page famously argued that if we suppose a black hole indeed operates with some unknown unitary evolution, then typically the radiation entropy should start to go down at its half-life, in contrast to Hawking’s calculation. We refer to this tension past the Page time as the entropic information puzzle. The challenge is to derive the entropy curve that Page predicted, i.e. the Page curve, using a first-principle gravity calculation.

Recently, significant progress (see  here and here ) has been made to resolve the entropic information puzzle. (cf. this review article and the references therein.) The entropy of radiation is calculated in semiclassical gravity with GPI à la Hawking, and the Page curve is derived. Remarkably and unexpectedly, the Page curve can be obtained in the semiclassical regime without postulating radical new physics. The new ingredient is the replica trick, which essentially probes the radiation spectrum with many copies of the black hole. The idea is that we’d like to compute all the moments of the radiation density matrix \mathrm{Tr}\rho^n=\mathrm{Tr}\rho^{\otimes n}\eta_n, where we rewrite it as the expectation value of the n-fold swap operator \eta_n on n identical and independent replicas of the state \rho. The trouble is we don’t know explicitly what \rho is, rather our current understanding of quantum gravity only allows us to describe the moments we’d like to compute implicitly in terms of a n-replica partition function with appropriately chosen boundary conditions.
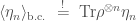
\langle\eta_n\rangle_\mathrm{b.c.}\ \stackrel{!}{=}\ \mathrm{Tr}\rho^{\otimes n}\eta_n

where the LHS is what we really compute in gravity and we postulate on the RHS that this partition function gives the moments of \rho that we want.

To evaluate \langle\eta_n\rangle_\mathrm{b.c.}, the GPI sums over all legit configurations, such as all sorts of metrics, topologies, and matter fields, consistent with the given boundary conditions. In particular, new geometric configurations show up and modify Hawking’s result. These geometries connect different replicas and are called replica wormholes. Since Hawking only ever considered a single black hole scenario, he missed these wormhole contributions in his calculation. In practice, performing the GPI over all the wormhole configurations can be technically difficult and one needs to resort to some simplifications and approximations. For the entropy calculation, one often drops all the wormholes but the maximally symmetric one that connects all the replicas. This approximation leads to a handy formula, called the island formula, for computing the radiation entropy and thus the Page curve. However, we should keep in mind that sometimes this approximation can be bad and the island formula needs a large correction. It would be interesting to see when and how this happens.

Fortunately, there is a toy model of an evaporating black hole due to Penington-Shenker-Stanford-Yang (PSSY), in which one can resolve the spectrum of the radiation density matrix without compromise. This model simplifies the technical setup as much as possible while still keeping the essence of the entropic information puzzle. This recent paper computes the radiation entropy by implementing the full GPI and identifies the large corrections to the commonly used island formula. Interestingly, the key ingredient is free probability.  The GPI becomes tractable after being translated into the free probabilistic language. Here we summarise the main ideas. In the replica trick GPI, the wormholes are organized by the non-crossing partitions. Feynman taught us to sum over all contributions weighted by the exponential of the gravity action evaluated on the wormholes (wormhole contributions). Then the resulting n-replica partition function (i.e. nth moment of \rho), is equal to summing over the wormhole contributions, matching exactly with the free moment-cumulant relation. Therefore, the wormhole contributions shall be treated as free cumulants. Furthermore, the matter field propagating on a particular wormhole configuration (labeled by \pi) is organized by the Kreweras complement of \pi. Together the total contribution to the n-replica partition function from both the wormholes and the matter field on them amounts to a free multiplicative convolution. It is a convolution between two implicit probability distributions encoding the quantum information from the gravity sector and the matter sector. With this observation, one can then evaluate the free multiplicative convolution using tools from free harmonic analysis to resolve the radiation spectrum and thus the Page curve. 
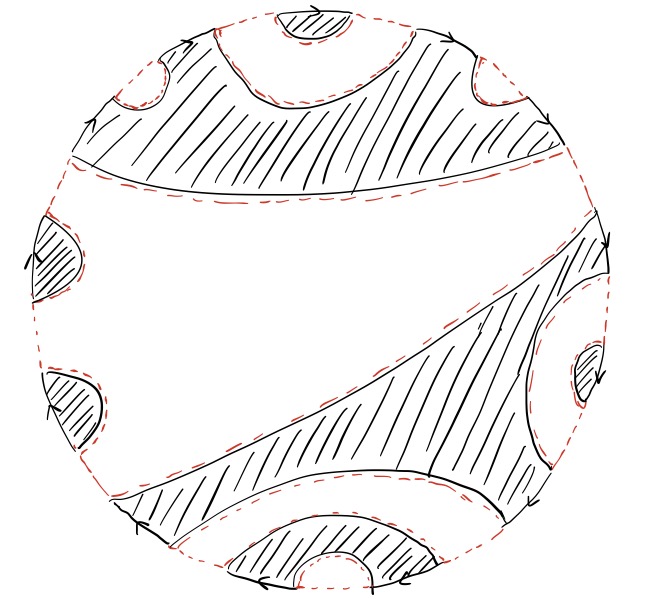
The figure illustrates a typical configuration for 13 replica black holes. The arrowed solid lines with length \beta indicate the boundary conditions that prepare each black hole in a thermal state of temperature 1/\beta; the dashed lines indicate the radiation quanta and they are cyclically connected to implement the observable \eta_{13}. Combinatorially, any wormhole configuration (in black) corresponds to a non-crossing partition and the configuration of the matter fields (in red) corresponds to the corresponding Kreweras complement.

Through modeling the free random variables in random matrices, we can go one step further and deduce from the convolution that the radiation spectrum matches the one obtained from a generalized version of Page’s model.  Therefore, we really start from the first-principle gravity calculation to address the challenge that Page posed, and free probability helps to make this connection clear and precise in the context of the PSSY model. What remains to be understood is why freeness is relevant here in the first place. To what extent is free probability useful in quantum gravity and is there a natural reason for freeness to emerge? Free probability already has applications in quantum many-body physics (cf. the previous post). If we think of quantum gravity as a quantum many-body problem, some aspects of it can be understood in terms of random tensor networks. This viewpoint has been very successful in the context of the AdS/CFT correspondence. In this view, freeness can plausibly be ubiquitous in gravity thanks to the random tensors. Another hint comes from concrete quantum mechanic models such as the SYK model, from which simple gravity theory can emerge in the low energy regime. The earlier work of Pluma and Speicher drew the connection between the double-scaled SYK model and the q-Brownian motion. Perhaps quantum gravity is calling for new species of non-commutative probability theories that differ from the usual quantum theory. 

There is a subtle logical inconsistency that we should address. The postulate above \langle\eta_n\rangle_\mathrm{b.c.}\ \stackrel{!}{=}\ \mathrm{Tr}\rho^{\otimes n}\eta_n is not exactly correct. The free convolution indicates that the radiation spectrum obtained is generically continuous, suggesting that we are dealing with a random radiation density matrix. Hence, in hindsight, it’s more appropriate to say that the GPI is computing the expected n-th moment \mathbb{E}\mathrm{Tr}\rho^{\otimes n}\eta_n. However, it is puzzling because this extra ensemble average \mathbb{E} radically violates the usual Born’s rule in quantum physics. 

In fact, we can give a proper physical explanation within the standard quantum theory. This was pointed out in this other recent paper, leveraging the power of the quantum de Finetti theorem. The key is to make a weaker postulate that the implicit state upon which we evaluate  \eta_n should be correlated instead of independent among the n replicas. Let’s denote this joint radiation state as \rho^{(n)}, which may not be a product state \rho^{\otimes n} as postulated above. This is because in the GPI \langle\eta_n\rangle_\mathrm{b.c.}, one only imposes the boundary conditions, so gravity could automatically correlate the state in the bulk even if one means to prepare them independently. It’s hence too strong to postulate that the joint radiation state implicitly defined via the boundary conditions has the product form \rho^{\otimes n}. Nonetheless, this joint state \rho^{(n)} should still be permutation-invariant because we don’t distinguish the replicas. Even better, it should also be exchangeable (meaning that the quantum state can be treated as a marginal of a larger permutation-invariant state) because we can in principle consider an infinite amount of replicas and randomly sample n replicas to evaluate \eta_n. This allows us to invoke the de Finetti theorem to deduce that the joint radiation state on n-replicas is a convex combination over identical and independent replica states \rho^{(n)}=\int d\mu(\rho)\rho^{\otimes n} with some probability measure \mu(\rho).

\langle\eta_n\rangle_\mathrm{b.c.}\ \stackrel{!}{=}\ \mathrm{Tr}\rho^{(n)}\eta_n = \int d\mu(\rho)\mathrm{Tr}\rho^{\otimes n}\eta_n.

The de Finetti theorem thus naturally brings in an ensemble average \int d\mu(\rho) that is consistent with the result of the free convolution calculation. Interestingly, one can further show that the de Finetti theorem implies that the replica trick really computes the regularized entropy \lim_{n\to\infty}S(R_1\ldots R_n)/n, i.e. the averaged radiation entropy of infinitely many replica black holes. It is to be contrasted with the radiation entropy of a single black hole, which can be much bigger because of the uncertainty in the measure \mu(\rho). The latter is closer to what Hawking calculated and he was wrong because the entropy contribution due to probability measure \mu(\rho) is not what we are after. This ensemble reflects that our theory of quantum gravity is incomplete to correctly pin down the exact description of the radiation, but we really shouldn’t attribute this uncertainty to the physical entropy of radiation. The gist of the replica trick is that with many copies the contribution from \mu(\rho) is moderated out in the regularized entropy because it doesn’t scale with the number of replicas. Therefore, when someone actually goes out and operationally measures the radiation entropy, she has to prepare many copies of the black hole and sample them to deduce the measurement statistics just like for measuring any quantum observable. Then she will find herself dealing with a de Finetti state, where \mu(\rho) acts like a Bayesian prior that reflects our ignorance of the fundamental theory. Nonetheless, the measurement shall reveal the truth and help update the prior to peak at some particular \rho. Hence, operationally the entropy measured should never depend on how uncertain the prior is. This is perhaps a better explanation of what Hawking did wrong.  These conceptual issues are now clarified thanks to the wisdom of de Finetti.

Free probability, between maths and physics

The fun of free probability is that if you think you have seen everything in the subject suddenly new exciting connections are popping up. This happened for example a few months ago with the preprints

Eigenstate Thermalization Hypothesis and Free Probability, by Silvia Pappalardi, Laura Foini, and Jorge Kurchan

and

Dynamics of Fluctuations in the Open Quantum SSEP and Free Probability, by Ludwig Hruza and Denis Bernard

According to the authors, the occurrence of free probability in both problems has a similar origin: the coarse-graining at microscopic either spatial or energy scales, and the unitary invariance at these microscopic scales. Thus the use of free probability tools promises to be ubiquitous in chaotic or noisy many-body quantum systems.

I still have to have a closer look on these connections and thus I am very excited that there will be great opportunity for learning more about this (and other connections) and discussing it with the authors at a special day at IHP, Paris on 25 January 2023. This is part of a two-day conference “Inhomogeneous Random Structures”.

Wednesday 25 January: Free probability, between maths and physics.
Moderator: Jorge Kurchan (Paris)

Free probability is a flourishing field in probability theory. It deals with non-commutative random variables where one introduces the concept of «freeness» in analogy to «independence» of commuting random variables. On the mathematical side, it has given new tools and a deeper insight into, amongst others, the field of random matrices. On the physics side, it has recently appeared naturally in the context of quantum chaos, where all its implications have not yet been fully worked out.

Speakers: Denis Bernard (Paris), Jean-Philippe Bouchaud (Paris), Laura Foini (Saclay), Alice Guionnet (Lyon), Frederic Patras (Nice), Marc Potters (Paris), Roland Speicher (Saarbrücken)

Another update on the q-Gaussians

There is presently quite some activity around the q-Gaussians, about which I talked in my last post. Tomorrow (i.e., on Monday, April 25) there will be another talk in the UC Berkeley Probabilistic Operator Algebra Seminar on this topic. Mario Klisse from TU Delft will speak on his joint paper On the isomorphism class of q-Gaussian C∗-algebras for infinite variables with Matthijs Borst, Martijn Caspers and Mateusz Wasilewski. Whereas my paper with Akihiro deals only with the finite-dimensional case (and I see not how to extend this to infinite d) they deal with the infinite-dimensional case, and, quite surprisingly, they have a non-isomorphism result: namely that the C*-algebras for q=0 and for other q are not isomorphic. This makes the question for the von Neumann algebras even more interesting. It still could be that the von Neumann algebras are isomorphic, but then by a reason which does not work for the C*-algebras – this would be in contrast to the isomorphism results of Alice and Dima, which show the isomorphism of the von Neumann algebras (for finite d and for small q) by actually showing that the C*-algebras are isomorphic.

I am looking forward to the talk and hope that afterwards I have a better idea what is going on – so stay tuned for further updates.

A dual and a conjugate system for the q-Gaussians, for all q

Update: On Monday, April 4, I will give an online talk on those results at the UC Berkeley Probabilistic Operator Algebra Seminar.

I have just uploaded the joint paper A dual and conjugate system for q-Gaussians for all q with Akihiro Miyagawa to the arXiv. There we report some new results concerning the q-Gaussian operators and von Neumann algebras. The interesting issue is that we can prove quite a few properties in a uniform way for all q in the open interval -1<q<1.

The canonical commutation and anti-commutation relations are fundamental relations describing bosons and fermions, respectively. In 1991, Marek Bożejko and I considered an interpolation between those bosonic and fermionic relations, depending on a parameter q with -1\le q \le 1 (where q=1 corresponds to the bosonic case and q=-1 to the fermionic case): a_ia_j^*-q a_j^* a_i=\delta_{ij} 1. These relations can be represented by creation and annihilation operators on a q-deformed Fock space. (Showing that the q-deformed inner product which makes a_i and a_i^* adjoints of each other is indeed an inner product, i.e. positive, was one of the main results in my paper with Marek.) In the paper with Akihiro we consider only the case where the number d of indices is finite.

Since then studying the q-Gaussians A_i=a_i+a_i^* has attracted quite some interest. Especially, the q-Gaussian von Neumann algebras, i.e., the von Neumann algebras generated by the A_i, have been studied for many years. One of the basic questions is whether and how those algebras depend on q. The extreme cases q=1 (bosonic) and q=-1 (fermionic) are easy to understand and they are in any case different from the other q in the open interval -1<q<1. The central case q=0 is generated by free semicircular elements and free probability tools give then easily that this case is isomorphic to the free group factor.

So the main question is whether the q-Gaussian algebras are, for -1<q<1, isomorphic to the free group factor. Over the years it has been shown that these algebras share many properties with the free group factors. For instance, for all -1<q<1 the q-Gaussian algebras are II1-factors, non-injective, prime, and have strong solidity. A partial answer to the isomorphism problem was achieved in the breakthrough paper by Guionnet and Shlyakhtenko, who proved that the q-Gaussian algebras are isomorphic to the free group factors for small |q| (where the size of the interval depends on d and goes to zero for d\to\infty). However, it is still open whether this is true for all -1<q<1.

In our new paper, we compute a dual system and from this also a conjugate system for q-Gaussians. These notions were introduced by Voiculescu in the context of free entropy and have turned out to carry important information about distributional properties of the considered operators and to have many implications for the generated von Neumann algebras.

Our approach starts from finding a concrete formula for dual systems; those are operators whose commutators with q-Gaussians are exactly the orthogonal projection onto the vacuum vector. If we also normalize such dual operators by requiring that they vanish on the vacuum vector, then the commutator relation gives a recursion, which can be solved in terms of a precise combinatorial formula involving partitions and their number of crossings, where the latter has, however, to be counted in a specific, and different from the usual, way. The main work consists then in showing that the dual operators given in this way have indeed the vacuum vector in the domain of their adjoints. The action of the adjoints of the dual operators on the vacuum gives then, by general results going back to Voiculescu and Shlyakhtenko, the conjugate variables.

One should note that whereas the action of the dual operators on elements in the m-particle space is given by finite sums, going over to the adjoint results, even for their action on the vacuum, necessarily in non-finite sums, i.e., power series expansions. Thus it is crucial to control the convergence of such series in order to get the existence of the conjugate variables. There have been results before on the existence of conjugate variables for the q-Gaussians, by Dabrowski, but those relied on power series expansions which involved coefficients of the form q^m for elements in the m-particle space and thus guaranteed convergence only for small q. In contrast, the precise combinatorial formulas in our work lead to power series expansions which involve coefficients of the form q^{m(m-1)/2}. This quadratic form of the exponent is in the end responsible for the fact that our power series expansions converge for all q in the interval (-1,1).

The existence of conjugate systems for all q with -1<q<1 has then, by previous general results, many consequences for all such q (some of them had been known only for the restricted interval of q, some of them for all q, by other methods). We can actually improve on the existence of the conjugate system and show that it satisfies a stronger condition, known as Lipschitz property. This implies then, by general results of Dabrowski, the maximality of the micro-states free entropy dimension of the q-Gaussian operators in the whole interval (-1,1).

Unfortunately, we are not able to use our results for adding anything to the isomorphism problem. However, the fact that the free entropy dimension is maximal for all q in the whole interval is another strong indication that they might all be isomorphic to the free group factor.